Public beta

The company brain that observes, reasons, and acts.

An events driven platform ingesting organizational activity into a knowledge graph for intelligent agentic outcomes.

onBrain

See it live

HOW onBrain WORKS

Observe. Reason. Act.

onBrain turns real-time activity across your organization's third-party applications into a living knowledge graph. This graph becomes the context that grounds how agents plan, decide, and act. Humans can also query company knowledge to understand past activity, tools that have been built, and how decisions were made; all while maintaining proper access control.

01 · INGEST

Every signal, normalized.

Event hooks into workplace tools such as Slack, GitHub, Jira, and more feed into one ingestion pipeline. Messages, PRs, tickets, and employee changes arrive as normalized, disambiguated events with a consistent format. Identities of those involved are resolved across platforms.
SlackGitHubJiraHRISonBrain

02 · GRAPH + ANALYZERS

A graph of who does what.

onBrain extracts meaningful labels, connections, and metadata from events which are written to a graph database. Dozens of analyzers sit on top of the graph to produce meaningful insights, hands free as events flow in.

03 · FINDINGS + ACTION

Context-driven action.

As findings flow in, action proposals are made. Personalized configurations dictate whether issues require approval or can initiate auto-implementation of solutions to remediate problematic findings.

Approval requiredskill · route_jira_ticket

Route TASK-84 from Backlog to Ingest / P1 with owner @sam.

single-use · audited

How the graph reasons

Every finding is grounded in real evidence.

A raw event becomes a typed, evidenced finding through one pipeline. Analyzers can only cite concrete identifiers pulled from the graph — issue keys, repos, people. If a claim can't be grounded back to observable facts, the runtime drops it. No phantom findings.

Ingest

Normalize events

→

Extract

Entities + links

→

Graph

Written with valid_at

→

Analyze

Reason over event

→

Act

Proposed under approval

Actual analyzer output

// scenario D3 — Identity + Compliance
{
  "analyzer": "DuplicateWorkAnalyzer",
  "severity": "high",
  "description": "kyc-compliance and
    kyc-service are building independent
    OFAC screening + identity scoring.",
  "action": "Coordinate before expanding scope",
  "evidence": ["org/kyc-service", "org/kyc-compliance",
    "SEC-2201", "INFRA-4821"],
  "confidence": 0.92
}

Typed & severity-scored

Findings are structured objects, not prose — routable, filterable, and machine-actionable.

Evidence you can click

Every finding names the exact repos, tickets, and people it was derived from.

Grounded or dropped

Claims that can't be tied to graph context never reach you. Precision over volume.

Product

Infrastructure, not another wiki

Org SnapshotsToday
TeamRepoPersonPRIssueDocDecision
Bi-temporal graph

Replay any past org state

Every fact carries a valid_at timestamp. Nothing is destructively edited — ask what the org looked like on any date.

Agent-callable · MCP
Claude Desktop→ onBrain MCP
search_nodes("auth-service owner")
onBrain ←result
{ owner: "jane", cites: [PR #418] }
MCP-native

Agent-callable by default

Claude Desktop, Cursor, or any LLM agent queries the graph and invokes skills over MCP — no bespoke integration code.

Entity Resolution
GitHub:jane_doeSlack:jdoe3Jira:jane-doeHRIS:jane.doeJDPerson: Jane Doe
Identity

One person, one node

Automated entity resolution for disparate 3rd party accounts ensuring a consistent, unified identity - so ownership questions just work.

Retrieval
Vector Search
Keyword Matching
Graph Walk

Findings must cite real repos, tickets, and people — or they're dropped.

Grounded search

Hybrid retrieval, no phantoms

Vector search + keyword matching + graph traversal. Every finding cites concrete identifiers from the graph or it never fires.

Configured Action
PolicyRaise ticketapprovedBuild featuregatedMerge codeblockedIngest Slack DMignored
Trust

Approval-gated & fully audited

Automated action fires on pre-approved scopes while remaining actions wait behind human approval gates - fully logged and traceable

Access control
Q3 roadmap · #productvisible
auth-service design docvisible
Comp & leveling · Peoplehidden
M&A discussion · #exechidden

Answers respect each person's permissions.

Access control

Right knowledge, right people

Identity-aware permissions control what someone should or shouldn't see to expose as much context as possible without compromising security.

See it live

From a Slack message to a filed ticket — in seconds.

An agent sees the gap, drafts the action, a human approves, and it ships — then the graph updates itself. This is the whole loop, end to end, with a human in the middle of every mutation.

SR

Sofia Reyes #platform-arch

Let's write a jira ticket for the auth-service rewrite. Neil can take this.

Approval requiredskill · route_jira_ticket

Create AUTH-412— “Auth-service rewrite”, assign @neil, label auth-service, link back to the Slack thread.

ApproveDenysingle-use · audited

Jira

waiting…

Knowledge graph

waiting…

Timeline

  1. Slack message arrives in #platform-arch

  2. Fast-path analyzer detects the trigger phrase

  3. Searches existing Jira — no matching ticket

  4. Approval card appears with a human-readable preview

  5. Human clicks Approve on a single-use token

  6. Ticket filed — assigned, labeled, linked to the thread

  7. Graph hydrates the new node; next query returns it

Surface → Remediate

See everything. Change only what you approve.

A fleet of analyzers reads every event and surfaces what matters — read-only, always-on. A focused set of skills then remediates, and every mutation waits behind a human approval gate.

What onBrain surfaces

Read-only · always-on

  • Blast radiusRisk

    The downstream services and teams a change actually touches.

  • Merge & deployment riskRisk

    Missing reviews, recent incidents, and high-churn hot spots.

  • Compliance issuesCompliance

    PII / HIPAA / SOC2 paths changed without the required review.

  • Stale & orphaned workWork

    Issues and PRs open far past the team's own norm.

  • Duplicate workWork

    Someone already solving the same or an adjacent problem.

  • Untracked bugs & to-dosWork

    Defects and meeting commitments with no owner in the graph.

  • Documentation driftKnowledge

    Docs contradicted by recent PRs, deploys, and schema changes.

  • Workload bottlenecksPeople

    Overloaded owners while relevant experts sit underused.

  • Planning assistanceWork

    Missing required plans, suggested design revisions, and cross-team coordination recommendations.

Approval gate

What onBrain remediates

Mutating · human-approved

  • Route inbound ticketsShipped

    Intelligently routes follow-up actions and untracked work as tickets.

  • Implement code fixesShipped

    Reads a linked issue, retrieves context, writes code, and opens a PR to review.

  • Nudge owners regarding stale workRoadmap

    Pings the owner of a stalled ticket or PR with a graph-derived reason it stalled.

  • Initiate cross-team communicationRoadmap

    Opens a thread between teams when duplicate work is planned or timeline coordination is required.

  • Escalate incidentsRoadmap

    Routes to on-call by graph-derived severity — pages only on confirm.

  • Implement onboarding plansRoadmap

    Builds a role-tailored ramp plan from graph-derived owners, systems, and prior decisions.

  • Capture knowledge before offboardingRoadmap

    Prompts a departing employee to document the systems and decisions they hold while also notifying past and current teammates of their exit.

Validated end-to-end

Validated against a fully ingested synthetic organization.

~600

events ingested

PRs, tickets, messages, deploys

28

repos across 8 teams

in the synthetic org

311

findings

duplicate work, stale work, routing

220

identities resolved

across GitHub, Slack, Jira & HRIS

Measured in demo mode against public fixtures — customer numbers land with our first design partners. Every scenario asserts the expected finding, so the pipeline is regression-tested, not hand-picked.

onBrainKnowledgePeopleProjectsDecisionsIntegrations
Workspace hub
Category
Knowledge item
Cross-reference

FAQ

onBrain ships as proprietary software you run in your own VPC. Your data stays in your infrastructure. Entity extraction calls the LLM provider you configure; nothing is routed through us.

onBrain is identity-aware — every answer respects the asker's permissions. Someone only sees knowledge derived from sources they're already entitled to, so sensitive channels, repos, and HR data stay scoped to the right people.

Retrieval is grounded in the graph — vector search, keyword matching, and graph traversal combined. Every finding requires citations to be present — real repos, PRs, tickets, people — or it's dropped. You receive answers with evidence you can click through, not a plausible guess.

Yes — but only when you configure it to. By default, mutating actions are approval-gated: the agent proposes, a human approves. You can grant an agent autonomy for specific actions or scopes, then tighten or revoke that authority at any time — down to the individual skill.

The set of integrated tools is constantly evolving and onBrain can work toward connecting the integrations you need if they aren't yet supported. Reach out if you'd like a complete list of what's connected at any given moment.

onBrain backfills from your existing history on connect — pulling in past pull requests, tickets, and org data — so the graph starts populated with real context instead of empty and slowly learning.

The everyday user will most likely interface through our frontend dashboard, which supports question answering, graph viewing and traversal, agentic findings, and more. No technical skill is required.

onBrain ships an MCP server so any LLM agent can query the graph and call skills today with no bespoke glue code.

Every fact carries a valid_at timestamp and is never destructively edited — only superseded. That means you can replay the org's state at any point in time ("who owned auth-service in January?") and get a grounded, deterministic answer instead of whatever the current snapshot happens to say.

Where we're going

Six Month Roadmap

Everything below is roadmap, not shipped. If you'd like to influence what comes next, get in touch.

Expanded Integrations

  • Integrations with third-party tools are constantly expanding — new sources to ingest and new systems to act into.
  • Design partners drive prioritization; we build the specific connectors your stack needs.

Expertise & Knowledge Risk

  • Surface the "who knows what" layer from PR reviews and Slack history.
  • Knowledge-at-risk analyzer — flag institutional knowledge concentrated in a single person.
  • Auto-generate tailored reading lists to ramp new hires.

Autonomous Workflows

  • Nudges — DM the owner of a stalled ticket or PR, and ping the graph-derived best reviewer (approval-gated).
  • Harden end-to-end task completion — from issue to opened PR.
  • Spin up remote compute so agents can execute longer-running work.

Trust & Controls

  • Granular control over agent autonomy — grant or revoke authority per skill or scope.
  • Approval & audit-log UI so non-technical stakeholders can review and authorize actions.

Dashboard & Experience

  • Richer graph exploration and natural-language Q&A in the dashboard.
  • Findings triage — review, dismiss, and act on analyzer findings in one place.
  • Smoother product onboarding — usable with no technical skill.

Managed Deployment & Ops

  • Hosted/cloud deployment so design partners don't need to self-host.
  • Flexible deployment across VPC, cloud, and on-prem.
  • Usage metering and billing primitives.

The roadmap is shaped by the first three design partners.

Investors

Raising our pre-seed round.

We're raising our pre-seed to bring on design partners, harden the platform for production deployment, and kick off our go-to-market.

Why now

Agents are here — but they can't act intelligently without proper company context. Giving them that context is the next phase of how large businesses operate.

Validated direction

The thesis is proven, and the industry is visibly converging on company brains as the layer agents run on.

Why us

We have the engineering expertise to build it — and a working proof of concept that proves it. Capital lets us productionize, QA, and keep pace as the space accelerates.

Meet the Founders

We're building onBrain with our first design partners. If the org-memory problem is yours, we'd like to hear from you directly.

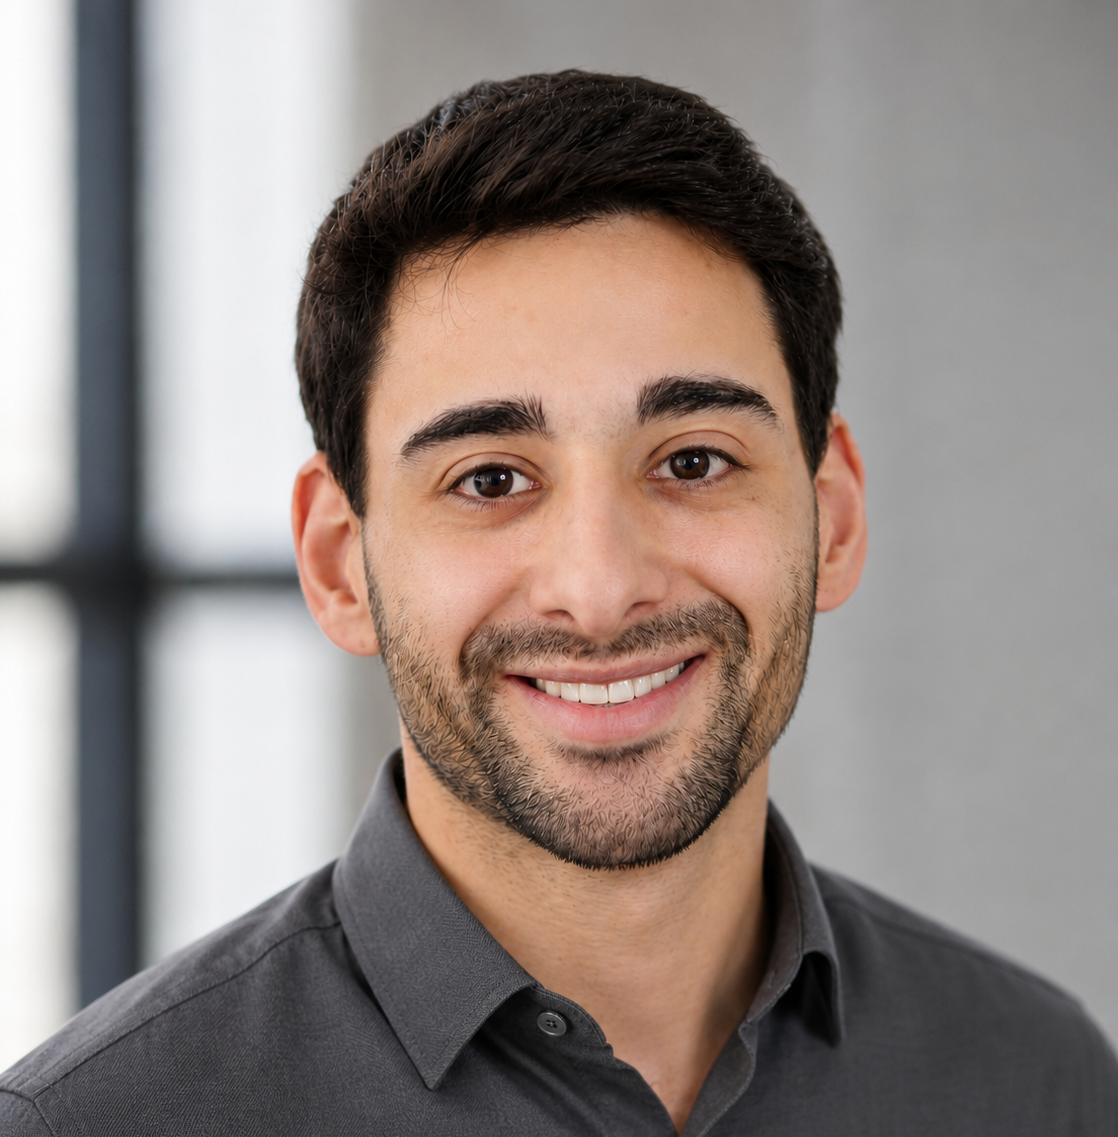
Neil Liberman — cofounder, ML Engineer at Apple

Neil

Technical founder and ML Engineer with 10+ years building scalable AI software at Apple and Accenture.

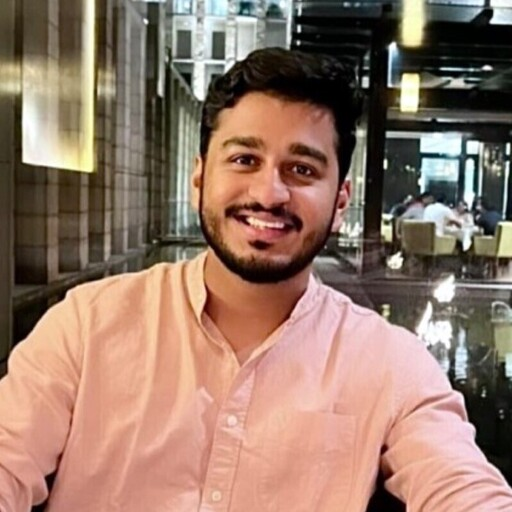
Prateek Mehta — cofounder, ML Engineer at Apple

Prateek

Technical founder. Leads retail and finance applications at Apple. PhD in Electrical and Computer Engineering.